LLM Research

LLM Research

Our LLM research teams investigate the safety, clinical accuracy, and patient impact of healthcare AI models, so that artificial intelligence improves access to care as it becomes increasingly capable.

LLM Research Papers Filter

TRADE: Transducer-Augmented Decoder for Speech LLM

OhioHealth partnered with Hippocratic AI to pilot a generative AI healthcare agent for pre-charting Medicare Wellness Visits, testing whether AI could match human PACT Outreach Coordinators while reducing charting burden and improving the patient experience. This study explores the results when OhioHealth deployed AI agents to administer a comprehensive pre-visit questionnaire covering lifestyle, SDOH, fall risk, general health, mental health, advanced directives, and medical equipment—improving documentation completeness ahead of primary care visits.
Read Our Paper

A Simple Plug-in for Improving Eviction-Based KV Cache Compression

A simple inference add-on that lets AI models handle long conversations with far less memory.

Read More

Generative Artificial Intelligence-Driven Voice Assistance for Patient Education in Ophthalmology

Patients and eye doctors gave high marks to a voice AI that teaches patients about eye-injection treatment.

Read More

Crafting Reversible SFT Behaviors in Large Language Models

A way to install a new behavior in an AI model — and cleanly switch it off later.

Read More

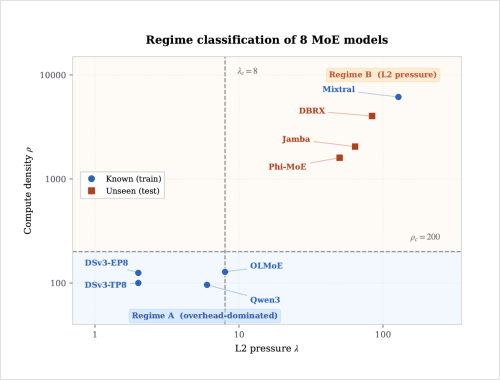
RaMP: Runtime-Aware Megakernel Polymorphism for Mixture-of-Experts

Makes the newest class of large AI models run significantly faster on the same hardware.

Read More

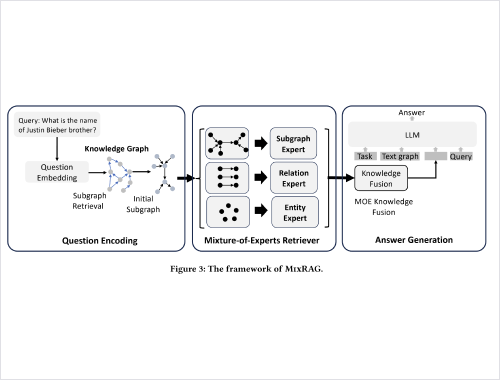
MixRAG: Mixture-of-Experts Retrieval-Augmented Generation for Textual Graph Understanding and Question Answering

Helps AI answer complex questions by pulling knowledge from many angles at once instead of one.

Read More

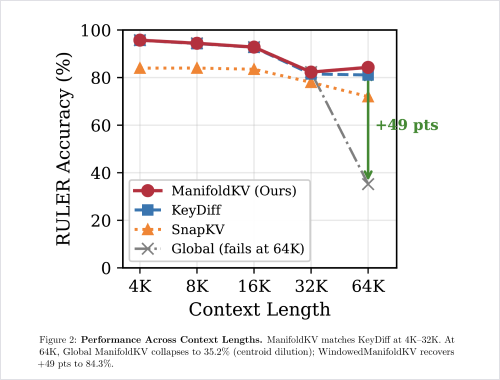
ManifoldKV: Training-Free KV Cache Compression via Euclidean Outlier Detection

Teaches AI models to keep the right memories — and drop the rest — during long conversations.

Read More

Perfecting Human–AI Interaction at Clinical Scale: Turning Production Signals into Safer, More Human Conversations

What 115 million real patient conversations taught us about making healthcare AI safer and more human.

Read More

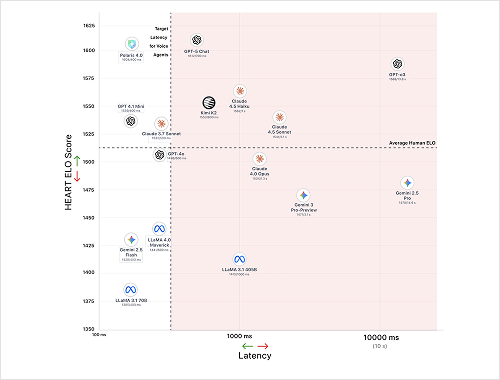
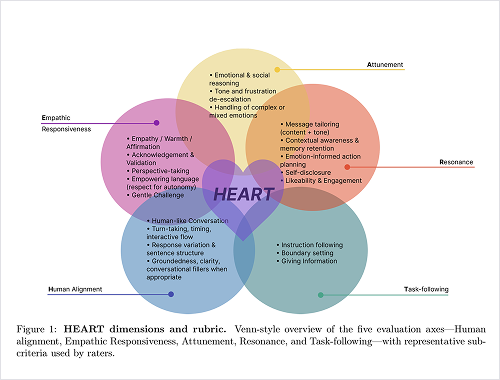
HEART: A Unified Benchmark for Assessing Humans and LLMs in Emotional Support Dialogue

The first benchmark measuring whether AI can genuinely emotionally support someone — scored side by side with humans.

Read More

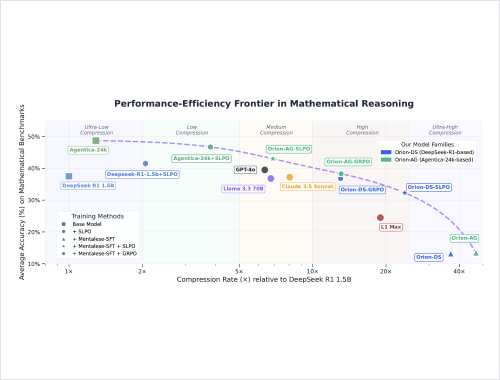
ORION: Teaching Language Models to Reason Efficiently in the Language of Thought

Teaches AI to think in shorthand instead of essays — same answers, dramatically faster.

Read More

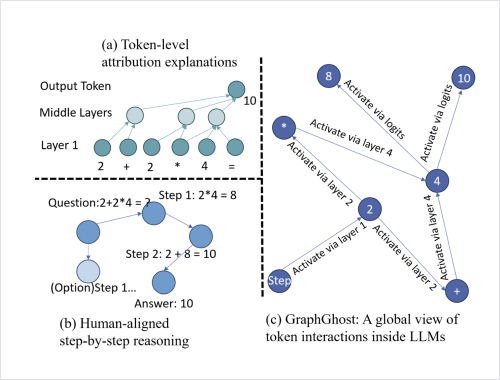
GraphGhost: Tracing Structures Behind Large Language Models

Opens the black box to reveal the hidden structure of how AI models reason step by step.

Read More